Run & evaluate
The scorecard
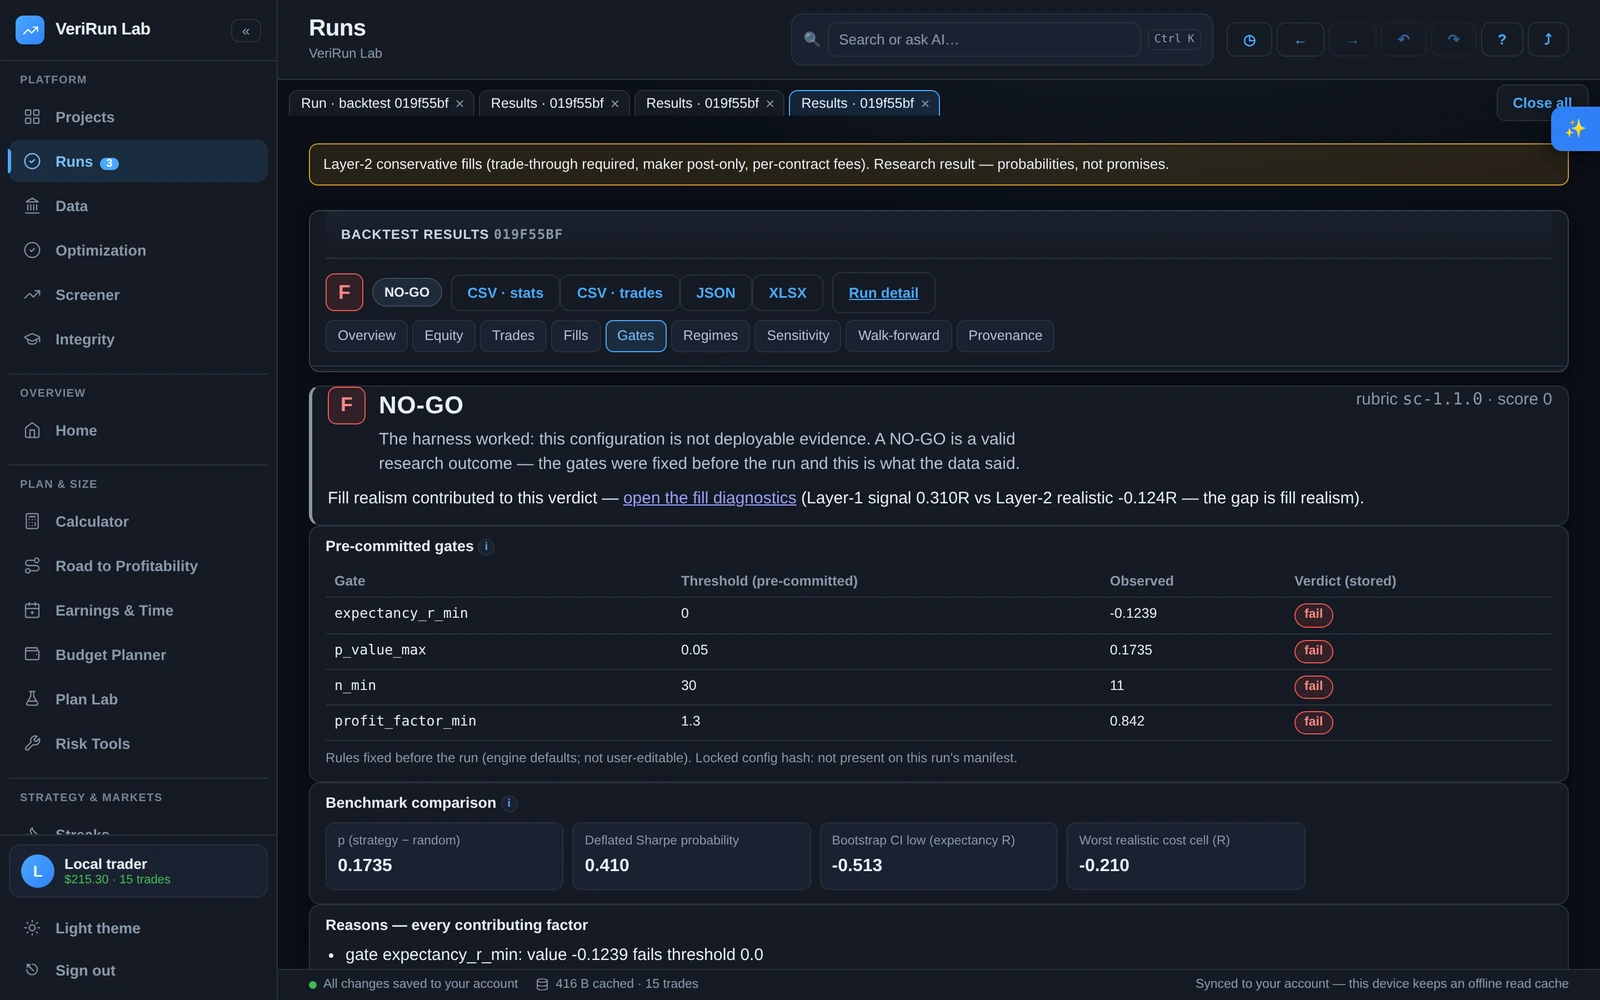
Every graded backtest ends in the Gates tab: a letter grade from A to F, a GO / NO-GO verdict, and the list of reasons that produced them. This page explains what the grade actually measures, how the gates work, and why a NO-GO is a result to respect rather than a bug to work around.
What A–F means
The grade measures evidence quality, not future profits. Its own tooltip says it plainly: “Research-quality grade — measures evidence quality, never promises performance.” An A says: this strategy produced strong, statistically defensible evidence under conservative assumptions on data it hadn't seen. It does not say the strategy will make money next month.
The grade is computed when the run finishes, against a versioned rubric that is displayed with the result (e.g. rubric v3 · score 71). The rubric's inputs are shown on the same page, so you can see what fed the letter:
- The pre-committed gates table — each gate with its threshold (fixed before the run; not user-editable), the observed value, and a pass/fail verdict. The note on the table says it all: “Rules fixed before the run.”
- The benchmark comparison — how the strategy's result stands against chance: the probability the edge over random entries is luck, a deflated Sharpe probability (which accounts for how many things you tried), a bootstrap confidence interval on expectancy, and the worst realistic-cost scenario.
The verdict basis — one label on every graded result
Every graded result carries the method that graded it. Legacy is the older method: the idealized pass's trades were the strategy side of the beats-random test and chose what the realistic engine saw. Realistic host is the current method for engine-native strategies and, since 2026-10-22, the built-in templates: the realistic engine alone is the strategy side of every statistic, R is read from each trade's own stop order, and the “random entries” replay the strategy's own exit orders at random entry times on the same exchange model — no fast pass, no declared geometry. A stored run without a label reads as legacy; nothing is regraded.
The basis is also the unit label. When every trade had a fully covering stop, the run is graded in R. When some trade had none, R is undefined: the R bands are left unscored and named, the run is graded on dollar statistics (profit factor, the beats-random test in dollars, the deflated Sharpe, sample size), expectancy in dollars is the headline, and the fix is one sentence — place a stop order for every entry. Two results on different bases, or in different units, are not like for like: the compare page, the library and the boards say so with a chip, and a strategy whose lineage holds both kinds shows a notice with a one-click re-run on the current basis (in-sample runs only — a held-out evaluation is never re-run) that stands beside the older run, never replacing it.
GO, NO-GO, and NOT EVALUATED
The verdict chip takes one of three values:
| Verdict | What it means |
|---|---|
| GO | Every pre-committed gate passed on the held-out evaluation. The app still reminds you: “Still a research result — probabilities, not promises.” |
| NO-GO | At least one pre-committed gate failed. The verdict caps the grade — a strategy cannot fail a hard gate and still wear an A. |
| NOT EVALUATED | Only in-sample evidence exists — the reserved holdout window hasn't been evaluated yet, so no verdict exists. Important nuance, straight from the app: “Absence of a NO-GO is not a pass.” |
Why a NO-GO caps the grade
The gates encode the failures that make a strategy undeployable no matter how pretty its equity curve is: an edge indistinguishable from luck, an edge that evaporates under realistic costs, drawdowns beyond tolerance. Letting a high “score” on other dimensions average away a failed hard gate would be exactly the kind of grade inflation the product exists to prevent. So the cap is absolute: fail a gate, cap the grade.
The reasons list
Under the verdict, “Reasons — every contributing factor” lists exactly why the verdict is what it is — each failed gate, each contributing diagnostic, verbatim as the grader recorded them. Read it as a work list, not a rejection letter:
- Reasons about statistical strength (edge vs. random, sample size) usually mean: not enough trades, or an edge too thin to distinguish from luck in this window.
- Reasons about costs and fills mean the idea survives idealized fills but not realistic ones — see the fill gap below.
- Reasons about risk (drawdown gates) mean the path to the profit was too painful to be tradable, whatever the endpoint says.
The fill-realism gap (runs graded on the legacy basis)
On a run graded the legacy way, when fill realism contributed to a verdict, the scorecard says so explicitly and points you at the fill diagnostics — e.g. an idealized-fills signal of 0.42R versus a realistic -0.05R. That gap is the finding: the pattern may be real, but the money was in fills you wouldn't actually have gotten. Strategies that rest passive limit orders at popular levels are the classic case.
Why an honest NO-GO is the system working
The app's own NO-GO copy is worth quoting in full, because it is the product's philosophy in three sentences:
What a NO-GO means
“The harness worked: this configuration is not deployable evidence. A NO-GO is a valid research outcome — the gates were fixed before the run and this is what the data said.”
Most backtesting tools let you keep adjusting until the report looks good — which silently converts “research” into curve-fitting. VeriRun Lab's gates are fixed before the run precisely so the answer can be no. Every honest NO-GO means the harness stopped you from deploying (or trusting) something the data didn't support. That's not friction; that's the product. The productive response to a NO-GO is to read the reasons, form a hypothesis, change the strategy (not the thresholds — you can't), and run again. Your previous runs stay in the library as the record of what you've already ruled out.
Context the scorecard also shows
- Data-quality warnings — if the run consumed data with known validation flags, the scorecard says so; treat the result with corresponding care.
- Stress findings — outcomes from the stress battery are shown alongside, but clearly labeled as hypotheses: they never change the stored grade or verdict. How to read them is covered in the run library guide.
- Days and streaks — the Overview’s Days and Streaks and trades blocks (day win %, green and red days, streaks, payoff ratio, hold time) and the weekday-and-hour table sit beside the scorecard. They are stored with the run and never change its grade or verdict; how they are counted is in Backtest results at a glance.
- “How to read this” — most panels carry a collapsible plain-language reading guide. When in doubt, open it; the guides are written for exactly the question you're about to ask.
The deep audit — a second, heavier battery
Every finished run gets the standard audit battery automatically — twelve checks on the Audit tab, each rendered as a plain-language chip with its severity and reasoning. When you want more than that, the same tab offers a deep audit: an on-demand, simulation-heavy pass (hundreds of re-runs of your strategy under noise, against null baselines, across shifted start dates, and over a walk-forward matrix). It takes a few minutes and ends in a deep verdict stored with the run. Since 2026-10-22 every one of those simulations is a real run of your strategy on the run's own simulated exchange, and the “against random” part replays your strategy's own exits from random entries — for engine-native strategies and built-in templates (an old-form plugin's run is refused by name). The simulation counts are a platform setting, and an audit too large for the platform's budget is refused before it starts, with the reason.
- A deep verdict is never silently downgraded. If a lighter re-audit runs later, its result is recorded in the history, but the run keeps showing the deep verdict.
- Publishing requires it. The publish checklist won't pass on the standard battery alone.
The independent AI review — a fresh set of eyes, told to refute
Separately from the audits, you can request an independent review from the run's page: a reviewer model in a fresh context, given the stored record and explicitly instructed to try to knock the result down rather than praise it. The verdict is stored with the run alongside the audits.
Because the review is a real model call, it sits behind an approval dialog that names it plainly as one billable call under your AI quota before anything is spent — the same approve-before-spend rule as everywhere else on the platform.